
ChatGPT for Financial Services Explained: Built-In Data, GPT-6 Astra, Firm Templates, Citations, and Governance Boundaries
What OpenAI Launched on September 10
On September 10, 2026, OpenAI introduced ChatGPT for Financial Services as a tailored ChatGPT Work product for eligible financial institutions. The launch should not be read as a normal consumer ChatGPT feature drop, a general-purpose model release, or a self-service subscription upgrade. OpenAI describes it as a financial-services-specific workspace that combines GPT-6 Astra, built-in financial data, optimized provider connections, research and modeling workflows, artifact generation, firm templates, and enterprise governance controls.
The initial business focus is investment banking and equity research, two domains where knowledge work routinely blends large volumes of source material, market data, spreadsheet modeling, client-ready narrative output, and review-heavy approval paths. In practical terms, OpenAI is positioning the product around workflows such as earnings transcript review, comparable company research, company and market backgrounding, model-adjacent analysis, presentation drafting, and source-backed research synthesis. The important boundary is that these are assistance workflows, not a delegation of regulated analyst responsibility or investment judgment to the model.
The launch also matters because OpenAI is separating a financial-institution product from a generic model capability. GPT-6 Astra is part of the product, but the product is not just “GPT-6 Astra with a finance prompt.” The financial-services package includes indexed data, citation behavior, provider connections, Office artifact generation, administrator-published templates, identity controls, retention controls, and compliance-log export options. That packaging is what makes the product operationally different from giving analysts access to a powerful model in an ordinary chat surface.
The article explains GPT-6 Astra for enterprise work, including computer use, plugins, cost per task, admin controls, and deployment boundaries. The complete GPT-6 Astra for Enterprise Work: Computer Use, New Plugins, Cost per Task, Admin Controls, and Deployment Boundaries article provides the destination-specific detail for this section’s GPT-6 Astra Enterprise Guide decision because this is the closest match for a marker about GPT-6 Astra in enterprise financial-services settings because it focuses on the operating model and controls enterprises need.
Eligibility Is a Product Boundary, Not a Footnote
OpenAI says ChatGPT for Financial Services is available only to eligible financial institutions through sales and account teams. That means administrators should not assume the product appears automatically in every ChatGPT Work, Business, Enterprise, or API environment. Eligibility, contracting, data entitlements, governance configuration, and deployment scope are part of the buying and rollout process. For a bank, asset manager, private-markets firm, broker-dealer, or research organization, this makes the first implementation question administrative rather than technical: is the institution eligible, and which workspace or population is in scope?
This boundary is especially important for teams comparing public model documentation with enterprise product behavior. A model page can describe a model family; it does not grant access to a financial-services workspace, bundled data, firm templates, or provider-specific integrations. Similarly, the presence of ChatGPT Work and Codex documentation does not mean every workplace feature, connector, or governance capability is active in a particular tenant. OpenAI’s launch framing places ChatGPT for Financial Services inside a managed institutional deployment path, not a do-it-yourself prompt pack.
For enterprise administrators, the eligibility boundary changes the rollout checklist. Before evaluating analyst prompts or research templates, the institution needs to clarify contracting status, covered business units, workspace segmentation, identity integration, permitted datasets, approved connectors, retention settings, and review procedures. A front-office proof of concept that ignores those gates can create avoidable conflicts with information-barrier policies, recordkeeping expectations, vendor-risk workflows, and data-provider license terms.
Operational reading: treat the September 10 launch as a specialized ChatGPT Work product for qualifying institutions, not as evidence that every ChatGPT user can access premium financial data, banking templates, or enterprise governance controls.
Why Investment Banking and Equity Research Are the Starting Point
Investment banking and equity research are natural starting domains because their work products are structured, source-heavy, and time-sensitive. A banking team may need to move from company materials and market background to an internal memo, valuation discussion, draft slides, or diligence question list. An equity research team may need to review earnings transcripts, filings, financial statements, news, sector context, and historical fundamentals before drafting a note or refreshing an internal view. In both cases, the value is not only in generation; it is in retrieving the right material, keeping citations attached, and producing artifacts in formats the institution already uses.
OpenAI’s launch notes built-in data from providers including Daloopa, PitchBook, LSEG News, and Crunchbase, with coverage described around earnings transcripts, financial statements, fundamentals, private companies, and related material. OpenAI says this data is indexed and hosted by OpenAI to improve retrieval and support granular citations. That architecture is significant because it gives the product a finance-specific knowledge substrate rather than relying only on user uploads, general web retrieval, or an analyst’s manual copy-and-paste workflow.
The starting focus does not make the product a universal authority on securities, issuers, markets, or transactions. Financial professionals still need to reconcile source documents, confirm data definitions, verify dates and periods, check issuer-specific adjustments, and apply firm methodology. A transcript excerpt, a private-company profile, a fundamentals table, or a news item can be useful evidence, but it does not automatically satisfy suitability obligations, research-supervision requirements, conflicts review, MNPI controls, or investment-committee standards.
The article provides 10 GPT-5.5 prompts designed for financial analysis and reporting automation workflows. The complete 10 GPT-5.5 Prompts for Financial Analysis and Reporting Automation article provides the destination-specific detail for this section’s Financial Analysis Prompt Guide decision because it directly supports the marker’s reader outcome by offering finance-specific analysis and reporting prompts rather than a general AI prompt collection.
Built-In Data Versus Subscription Entitlement Integrations
The launch has two different data concepts that should not be collapsed. First, OpenAI describes built-in data from named providers that is indexed and hosted by OpenAI for the financial-services product. Second, OpenAI says separate entitlement integrations are being developed for existing subscriptions from providers including S&P Capital IQ, LSEG, MSCI, Dow Jones Factiva, and Moody’s. The wording matters: built-in launch data is not the same as every institution’s existing market-data contract becoming instantly available inside ChatGPT.
For procurement and data-governance teams, this distinction drives the license review. Built-in datasets require understanding what is included in the product, who can access it, what citations expose, and how usage aligns with the institution’s approved purposes. Existing-subscription integrations require a separate entitlement analysis: which users are already licensed, what provider terms allow, whether redistribution is restricted, and how access should be revoked when a user changes role. OpenAI’s broader connector ecosystem, described as more than 50 connectors, is another separate category; a connector ecosystem is not equivalent to bundled premium financial data.
| Data or access layer | What OpenAI described | Governance question for financial institutions |
|---|---|---|
| Built-in financial data | Named launch providers include Daloopa, PitchBook, LSEG News, and Crunchbase, covering materials such as earnings transcripts, financial statements, fundamentals, private companies, and related data. | Which user groups may use the included data, and what review process verifies citations, definitions, dates, and licensing constraints? |
| Existing-subscription entitlement integrations | OpenAI says integrations are being developed for subscriptions from providers including S&P Capital IQ, LSEG, MSCI, Dow Jones Factiva, and Moody’s. | Which integrations are actually enabled for the institution, and how are provider entitlements mapped to individual users or groups? |
| Broader connector ecosystem | OpenAI references a connector ecosystem of more than 50 connectors. | Which connectors are approved, read-only or write-capable, logged, and appropriate for regulated workflows? |
The Design-Partner Role: Useful Signal, Not a Universal Benchmark
OpenAI’s launch includes design-partner statements and productivity claims, but those should be treated as product-development signal rather than independent proof of universal performance. In a design-partner model, selected institutions help shape workflows, test assumptions, and surface domain-specific requirements. That input can be valuable because investment banking and equity research have specialized output formats, review norms, terminology, data dependencies, and permission boundaries that a generic assistant may not satisfy out of the box.
Design-partner involvement does not remove the need for each institution to run its own evaluation. A global bank, a boutique advisory firm, a long-only asset manager, and a private-markets research team may all use financial data differently. Their compliance obligations, information barriers, template standards, supervisory workflows, and provider licenses can differ materially. A claim that one design partner found a workflow useful does not prove the same workflow is suitable, approved, or accurate in another environment.
OpenAI also published a vendor benchmark result: ChatGPT for Financial Services is reported at 69.9% on OfficeQA Pro versus 60.2% for GPT-5.6 Sol. That result is useful as a vendor-published directional indicator, but it should not be converted into a service-level guarantee or a prediction of a specific team’s productivity. Office-style question answering is not the same as a regulated research approval process, a merger model review, a fairness analysis, or an investment recommendation.
A Tailored ChatGPT Work Product, Not a Generic Model Release
The simplest way to understand the launch is to separate four layers: the model, the data, the workflow surface, and the governance envelope. GPT-6 Astra is the reasoning and generation layer OpenAI associates with the product. Built-in financial data and provider connections shape what the product can retrieve. Research, modeling, and artifact workflows shape how users turn retrieved material into memos, spreadsheets, documents, or presentations. Enterprise controls shape who can access which capabilities, how identity is managed, what logs are available, and how retention is configured.
A generic model release usually asks developers and administrators to build those layers themselves. They choose the model, connect data, implement retrieval, design prompts, build review queues, manage document templates, integrate identity, configure retention, and monitor usage. ChatGPT for Financial Services packages more of that operating environment into a product aimed at eligible institutions. That packaging can reduce implementation burden, but it does not eliminate governance work. The institution still owns policy decisions, user training, quality review, data-license compliance, and regulated approvals.
OpenAI says administrators can publish Excel, Word, and PowerPoint templates and style guides. That feature is operationally important because financial-services output is rarely judged only by textual correctness. An investment-banking presentation may need firm-standard formatting, disclaimer placement, chart conventions, footnote style, and review routing. A research note may need consistent issuer naming, rating-language discipline, risk-factor placement, and source treatment. Firm-administered templates help align AI-generated artifacts with internal standards, but they do not certify the commercial, legal, or analytical content of the artifact.
Governance Boundaries in the Opening Frame
OpenAI lists enterprise controls including SAML SSO, SCIM, role-based access, configurable retention, Compliance Platform log exports, role-based control over skills and apps, read/write action controls, and multiple workspaces for information barriers. OpenAI also says business data is not used to train models by default and is encrypted at rest and in transit. These are meaningful enterprise controls, but each one must be configured and reviewed in the context of the institution’s policies. A control listed in a product announcement is not the same as a completed deployment design.
Multiple workspaces are especially relevant in financial services because information barriers are not cosmetic. A firm may need to separate banking teams from research teams, public-side activity from private-side activity, deal teams from non-deal teams, or regions with different supervisory requirements. Workspace design should be mapped to the firm’s actual barrier policy rather than to an org chart alone. The wrong grouping can expose users to data they should not see or create a misleading audit story after the fact.
Citations are another boundary feature. OpenAI says the built-in data is indexed and hosted in a way that enables retrieval improvements and granular citations. Granular citations can make analyst review faster by showing the source behind a statement, number, or claim. They do not prove that the cited material is the right source, the latest source, the licensed source for that user, or the complete context needed for a regulated conclusion. A citation workflow should include source reconciliation, period checks, document-version checks, and escalation when the cited evidence conflicts with firm-approved data.
How Financial Teams Should Read the Launch Before Piloting
The right first reaction is not to ask analysts to “try it on a live deal” or researchers to “replace their morning workflow.” The safer first step is a controlled workflow inventory. Identify which tasks are public-information research, which involve client confidential information, which may involve MNPI, which depend on licensed third-party data, which produce external communications, and which require supervisory approval. Tasks with high reversibility and clear source verification are better early candidates than tasks that create client commitments, regulated recommendations, or irreversible market-facing outputs.
A practical pilot should define the user group, approved data sources, blocked data classes, template set, required citations, review owners, escalation rules, and success criteria before users begin. For example, an equity research pilot might allow transcript summarization and variance-table drafting while prohibiting final rating language or price-target changes without analyst and supervisory review. An investment-banking pilot might allow company background pages and diligence-question generation while prohibiting unapproved client deliverables or transaction advice.
This article analyzes the product and its governance boundaries; it does not provide personalized investment advice, securities recommendations, or legal conclusions. The September 10 launch is important because it shows OpenAI moving from general workplace AI toward a domain-specific operating environment for finance. Its usefulness will depend less on whether the model can draft fluent text and more on whether each institution can align data access, citations, templates, review procedures, information barriers, and compliance evidence with the way regulated financial work is actually performed.
Data Access Architecture: Included Premium Data, Entitlements, MCP Connections, and Connectors
OpenAI describes ChatGPT for Financial Services as combining GPT-6 Astra with built-in financial data, provider connections, research workflows, artifact generation, firm templates, and enterprise governance for eligible financial institutions. The data architecture matters because a banker, research analyst, compliance officer, or technology administrator should not treat every source that appears in the product story as the same kind of entitlement. Some data is described as included and hosted by OpenAI; some provider integrations are described as being developed for firms that already subscribe; some connections are optimized for workflow access; and the broader connector ecosystem is a separate integration surface rather than a universal premium-data license.
The practical distinction is simple: “available in the workflow” is not the same as “licensed for every use, every user, every desk, every jurisdiction, and every output.” A valuation model that cites a transcript, a banking pitch that references private-company data, and an equity-research note that quotes news or consensus-adjacent material each create different licensing, compliance, and review questions. OpenAI’s launch positioning reduces retrieval friction, but firms still need source-level controls for redistribution, client use, research publication, conflicts review, and retention.
The Four Data Channels Financial Institutions Need to Separate
Included premium data is the clearest category in OpenAI’s launch. OpenAI names Daloopa, PitchBook, LSEG News, and Crunchbase as included data sources, with datasets spanning earnings transcripts, financial statements, fundamentals, private companies, and related material. OpenAI says this data is indexed and hosted by OpenAI, which is important because the retrieval layer can be tuned for the financial-services product and can support more granular citations than a general-purpose file upload or unmanaged web lookup.
Existing-subscription entitlement integrations are a different category. OpenAI says it is developing integrations for existing subscriptions from providers including S&P Capital IQ, LSEG, MSCI, Dow Jones Factiva, and Moody’s. That wording should be read carefully: it is not a claim that every named provider integration is generally live for every eligible institution, and it is not a claim that OpenAI is granting a new license to those datasets. A firm planning a pilot should ask its OpenAI account team and each data vendor which entitlements, users, content sets, geographies, export rights, and audit obligations apply.
Optimized MCP connections should be treated as a workflow and tool-access layer, not as a substitute for entitlement governance. Model Context Protocol connections can make external systems more useful to an agentic workflow by structuring access to tools and data sources, but the connection layer does not remove the need to authenticate the user, restrict permitted actions, log access, and confirm that downstream generated artifacts are allowed under the relevant data contract. A financial institution should map MCP tools to business owners, data owners, and compliance reviewers before allowing write actions or broad retrieval.
The broader connector ecosystem is still another category. OpenAI states that the broader connector ecosystem includes more than 50 connectors, but that ecosystem should not be conflated with the included premium financial datasets or with subscription-provider integrations under development. A connector to a productivity system, document repository, or collaboration platform may help Astra assemble a model, memo, or presentation, but it does not automatically validate the quality of the underlying files, cure permission sprawl, or create permission to commingle confidential client records with market data in a generated artifact.
| Provider or channel | Category in the launch framing | Status language to use internally | Operational implication | Minimum review control |
|---|---|---|---|---|
| Daloopa | Included premium data named by OpenAI | Described by OpenAI as included data indexed and hosted for the product | Useful for workflows involving financial statements, fundamentals, and structured company data where firm policy permits use | Verify citation coverage, period alignment, and redistribution limits before client-facing use |
| PitchBook | Included premium data named by OpenAI | Described by OpenAI as included data indexed and hosted for the product | Potentially relevant to private-company, transaction, investor, and market-mapping workflows | Confirm user entitlement, permitted output types, and treatment of private-company facts in external materials |
| LSEG News | Included premium data named by OpenAI | Named as included data; distinguish from separate LSEG subscription integrations | Can support news-aware research and monitoring workflows when citations are preserved | Review quotation, redistribution, embargo, and publication rules under the applicable license |
| Crunchbase | Included premium data named by OpenAI | Described by OpenAI as included data indexed and hosted for the product | Potentially useful for company profiles, startup ecosystems, investors, and competitive screens | Check recency, source provenance, and whether data is acceptable for regulated or client-facing conclusions |
| S&P Capital IQ | Existing-subscription entitlement integration | OpenAI says integrations are being developed; do not describe as universally live | May eventually connect a firm’s existing subscription entitlements into ChatGPT workflows | Require vendor-contract review, entitlement mapping, and usage logging before production reliance |
| LSEG subscription content beyond named LSEG News | Existing-subscription entitlement integration | OpenAI says integrations are being developed; keep separate from included LSEG News | Could support additional licensed datasets if the firm has the right subscription and the integration is available to that workspace | Confirm product module, user group, and export restrictions with LSEG and internal market-data teams |
| MSCI | Existing-subscription entitlement integration | OpenAI says integrations are being developed; do not treat as a default dataset | Potential relevance to index, portfolio, ESG, risk, or analytics workflows depending on subscribed content | Validate calculation methodology, license scope, and attribution requirements before derived outputs are distributed |
| Dow Jones Factiva | Existing-subscription entitlement integration | OpenAI says integrations are being developed; availability must be confirmed | Could support news, media, company, and diligence workflows for firms with appropriate entitlements | Review redistribution, quotation, archive, and publication controls before including excerpts in deliverables |
| Moody’s | Existing-subscription entitlement integration | OpenAI says integrations are being developed; do not claim general availability | Potential relevance to credit, ratings, risk, and issuer research if licensed and enabled | Require ratings-use policy review and explicit controls for client-facing, investment, or risk-committee materials |
| Optimized MCP connections | Tool and workflow connection layer | Connection mechanism; not itself a data license | Can expose approved systems or tools to a workflow when configured by the institution | Bind each tool to identity, permissions, logging, action limits, and human approval rules |
| More than 50 broader connectors | Connector ecosystem | Separate from included premium data and subscription-provider entitlements | Can connect productivity, repository, or enterprise systems subject to administrator configuration | Audit repository permissions, file sensitivity, retention expectations, and output destinations |
Granular Citations Improve Traceability, Not Accountability
OpenAI says the included data is indexed and hosted by OpenAI, enabling retrieval improvements and granular citations. In financial work, that is a material product-design choice because analysts often need to know whether a number came from a filing-derived statement, an earnings transcript, a news item, a private-company profile, or a spreadsheet already controlled by the firm. Granular citations can reduce time spent hunting for provenance, but they do not prove that the generated conclusion is complete, compliant, or analytically sound.
A citation should be treated as a pointer to evidence, not as a legal opinion, investment conclusion, or quality seal. If ChatGPT produces a paragraph saying revenue accelerated, margins contracted, and management lowered guidance, the analyst still needs to verify the cited periods, review the cited passages, check whether the cited source is the latest available version, and determine whether the language is appropriate for the intended audience. The same discipline applies to model outputs: a cited historical revenue figure does not validate the forecast assumptions built on top of it.
The review burden is higher when outputs blend multiple source types. A single paragraph might combine a Daloopa-derived financial metric, a PitchBook private-company fact, an LSEG News item, and a firm-uploaded banker note. That blend can be useful for productivity, but it also creates a source-reconciliation task: the reviewer must identify which assertions are market data, which are firm confidential information, which are analyst judgments, and which are generated synthesis. Firms should require the final deliverable to preserve citations at the claim level for any statement that is material to a recommendation, valuation, diligence finding, or client presentation.
The article covers source-controlled deep research prompts for plan review, domain filters, live steering, citation checks, and decision artifacts. The complete 25 ChatGPT-5.5 Prompts for Source-Controlled Deep Research: Plan Review, Domain Filters, Live Steering, Citation Checks, and Decision Artifacts article provides the destination-specific detail for this section’s Citation Verification Workflow decision because it is the strongest fit for a citation verification marker because its excerpt explicitly includes citation checks and defensible research outputs.
Source Reconciliation: What to Do When Trusted Sources Disagree
Financial datasets disagree for legitimate reasons. One provider may normalize non-GAAP measures differently, another may update private-company funding data on a different schedule, and a news source may report management commentary before a structured dataset reflects the same event. ChatGPT can surface multiple citations quickly, but a firm still needs a reconciliation policy that tells analysts which source wins for a given task and how exceptions are documented.
A practical reconciliation policy starts with a hierarchy. For public-company historical financials, the firm may prefer primary filings or a designated normalized-data provider. For market news, the firm may prefer the licensed news source that carries the original report and timestamp. For private-company information, the firm may require a confidence label because data may be self-reported, sourced from filings, inferred from transactions, or aggregated from public and private records. For ratings, index membership, or benchmark attributes, the firm should follow the provider’s official methodology and license terms rather than allowing a generated answer to blend incompatible definitions.
When two cited sources conflict, the user should not ask the model to “pick the best number” without criteria. A better procedure is to require a discrepancy table with source name, cited value, period, as-of date, definition, currency, unit, update timestamp if available in the source, and recommended treatment. The output should explicitly label whether the difference appears to be timing, methodology, restatement, currency conversion, segment definition, pro forma adjustment, or an unresolved conflict requiring human escalation.
Recommended analyst instruction for source reconciliation:

Create a discrepancy table for every material figure that differs across sources.
For each figure, show:
- source and citation
- value, currency, unit, and fiscal period
- as-of date or publication date available from the source
- definition used by the source
- likely reason for the discrepancy
- proposed treatment under our source hierarchy
- items requiring human review before external use

Do not resolve a conflict by averaging values unless the methodology explicitly allows it.
Do not remove a conflicting citation merely to make the narrative cleaner.
Period Alignment Is the Hidden Failure Mode in AI-Assisted Financial Work
Period alignment is one of the most common ways an otherwise well-cited draft can become wrong. A model may retrieve a fiscal-year number, a last-twelve-months figure, a calendar-year estimate, and a quarterly transcript comment in the same answer. Each item can be individually cited and still produce a misleading conclusion if the periods do not match. GPT-6 Astra’s work orientation and artifact-generation capabilities can help assemble tables and presentations, but the firm must still require period discipline in every model, chart, and memo.
The minimum period-alignment check should confirm fiscal year-end, reporting currency, actual versus estimate status, quarter versus annual period, restatement status, and whether a metric is GAAP, IFRS, non-GAAP, adjusted, pro forma, or provider-normalized. A banking team building a comparable-company analysis should not let one company’s calendar-year EBITDA, another company’s fiscal-year EBITDA, and a third company’s next-twelve-months estimate sit in the same multiple table without labels. An equity-research team should not compare guidance commentary from one quarter to realized financials from another period without saying exactly what changed.
Financial-services administrators can encode this discipline into templates and style guides. OpenAI says administrators can publish Excel, Word, and PowerPoint templates and style guides, which means a firm can require standard footnote language, source columns, as-of-date fields, period labels, and review checkboxes in generated artifacts. The important governance move is to make the template carry the control, not merely the branding. A polished PowerPoint slide without source, period, and ownership fields is a compliance risk even if it follows the firm’s visual style.
Data Licensing and Entitlements: The Pilot Checklist Before Production
Data licensing is not a back-office detail for this product category. If ChatGPT for Financial Services helps create investment-banking pitch books, diligence summaries, research drafts, or portfolio-monitoring artifacts, then licensed data may leave its original interface and appear in a generated output. That movement can trigger vendor-contract restrictions on redistribution, derived data, storage, excerpting, display, attribution, and client use. OpenAI’s product may provide a better user experience, but it does not eliminate the firm’s obligation to honor the data owner’s terms.
Before a production rollout, the market-data, legal, compliance, technology, and business owners should approve a provider-by-provider entitlement map. The map should identify which workspaces can access which sources, which user groups can retrieve them, which sources can be used in client-facing materials, whether excerpts can be quoted, whether derived metrics can be stored, and how long generated artifacts may be retained. The same map should define what happens when a user moves desks, loses a vendor entitlement, joins a restricted deal team, or attempts to use a connector from a workspace separated by an information barrier.
OpenAI’s launch states that enterprise controls include SAML SSO, SCIM, role-based access, configurable retention, Compliance Platform log exports, role-based control over skills and apps, read/write action controls, and multiple workspaces for information barriers. Those controls are relevant to licensing because entitlement mistakes are often identity and workspace mistakes. If a private-side banking team and a public-side research team share a workspace, connector, or generated artifact repository without appropriate barriers, the problem is not only model quality; it may be access control, MNPI handling, and information-barrier governance.
Operational recommendation: treat each premium data source, entitlement integration, MCP tool, and connector as a controlled system with its own owner, license scope, approved use cases, logging requirements, and output restrictions. Do not approve a workflow merely because the model returns citations or because the source appears in a configured connector list.
A Review Pattern for Cited Outputs in Banking and Research
A practical cited-output workflow should have three layers. First, ChatGPT produces the draft, table, model, or presentation with citations preserved for every material fact. Second, the analyst or associate performs source reconciliation and period alignment, including a check for missing citations and unsupported synthesis. Third, the approver reviews the business conclusion, suitability of language, conflicts status, information-barrier restrictions, and whether the output can be distributed to the intended audience under firm policy and data-provider terms.
For investment banking, the highest-risk points are usually client-facing claims, precedent-transaction screens, buyer lists, private-company descriptions, valuation ranges, and language that could imply certainty about market appetite or financing terms. For equity research, the highest-risk points include ratings, target-price support, earnings estimates, selective disclosure, quotation of news or transcripts, and inconsistencies between the cited source and the analyst’s published model. In both environments, citations help reviewers move faster, but the accountable professional still owns the conclusion.
The safest pilot design is to begin with internal drafts and controlled artifacts, not automatic external distribution. Teams should measure whether the product improves retrieval, drafting, and model-preparation workflows while deliberately sampling for citation errors, stale sources, period mismatches, license-sensitive excerpts, and unsupported recommendations. OpenAI’s product framing is strongest when it is used as a governed workbench for professionals who already understand the domain; it is weakest if a firm treats generated citations as an automated approval chain.
From Retrieval to Governed Work Product: How the Stack Should Operate
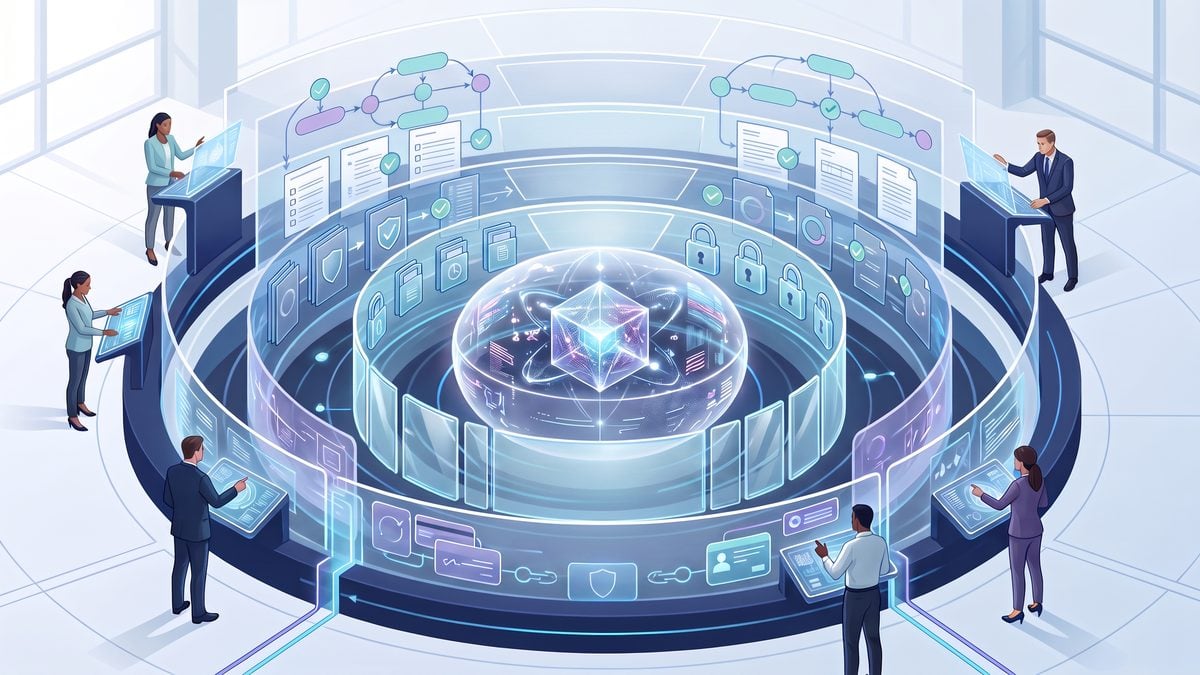
ChatGPT for Financial Services should be evaluated as a governed workflow system, not as a faster search box or a standalone reasoning model. OpenAI describes the product as combining GPT-6 Astra with built-in financial data, optimized provider connections, research and modeling workflows, artifact generation, firm templates, and enterprise controls for eligible financial institutions. The operational question for a bank, asset manager, or research department is therefore not “Can the model answer finance questions?” but “Can the institution define which data may be retrieved, how reasoning must be checked, which artifacts may be produced, which actions require approval, and which logs prove that policy was followed?”
Astra-assisted retrieval is most useful when the workflow distinguishes three steps that are often collapsed in manual analyst work: locating source material, extracting decision-relevant facts, and applying financial reasoning to a defined task. OpenAI says the built-in data includes sources from Daloopa, PitchBook, LSEG News, and Crunchbase, covering materials such as earnings transcripts, financial statements, fundamentals, private-company data, and related content. Because OpenAI says this data is indexed and hosted by OpenAI, retrieval can support granular citations; however, citations should be treated as a traceability layer, not as proof that the interpretation, period alignment, or downstream model formula is correct.
For practical deployment, financial teams should require the assistant to expose the retrieval path before accepting the analytical conclusion. A defensible output should show which company, period, metric, source document, and citation support each important claim. If the prompt asks for “revenue growth over the last four quarters,” the review standard should verify that the model did not mix fiscal and calendar periods, confuse reported and adjusted figures, or blend consensus, company-reported, and third-party standardized metrics without labeling them. This is especially important when the same term, such as EBITDA, net revenue, or assets under management, can be reported differently across sectors, providers, and internal templates.
Astra-Assisted Retrieval: What Should Happen Before the Model Reasons
A retrieval-first workflow should start with a narrow research contract. The analyst or banker should specify the issuer, peers, time horizon, filing or transcript type, geography, currency, accounting basis, and whether the output is for internal diligence, public research, client materials, or a regulated approval process. This upfront contract reduces the chance that GPT-6 Astra retrieves plausible but irrelevant information and then builds a polished narrative around it. It also gives reviewers a checklist for determining whether the answer used the right data universe.
The next step is source classification. Built-in premium data, provider entitlement integrations, firm-uploaded documents, connectors, and user-provided files should not be treated as interchangeable. OpenAI’s launch separates included built-in data from entitlement integrations being developed for existing subscriptions from providers including S&P Capital IQ, LSEG, MSCI, Dow Jones Factiva, and Moody’s. That distinction matters because licensing, redistribution, citation visibility, and user entitlements may differ across data classes. A retrieval result that is acceptable for internal analysis may not be acceptable for a client-facing deck or research note.
This connector setup guide explains how ChatGPT integrations with Slack, Google Drive, Jira, and other enterprise systems depend on authorization and workflow design, providing a practical baseline for evaluating financial-data entitlements and institution-controlled connectors. The complete How to Set Up ChatGPT Connectors for Automated Workflows: Integrating Slack, Google Drive, Jira, and 20+ Third-Party Apps with Scheduled Tasks article provides the destination-specific detail for this section’s Enterprise Data Connector Strategy decision because the target is an operational connector guide and is more useful than a speculative acquisition article for the entitlement discussion.
Financial reasoning should begin only after the model has produced a source map that a human can inspect. For example, a credit analyst asking for a covenant summary should require the assistant to identify the credit agreement sections used, quote or cite the relevant clauses, distinguish defined terms from ordinary-language paraphrases, and flag ambiguous interpretations. A banking associate asking for a comparable-company table should require the assistant to list each metric source, calculation formula, period basis, and any missing values rather than silently filling gaps with assumptions.
Financial Reasoning: Useful Acceleration, Not a Delegation of Judgment
OpenAI’s launch reports a vendor-published OfficeQA Pro benchmark result of 69.9% for GPT-6 Astra compared with 60.2% for GPT-5.6 Sol. That benchmark is relevant because financial professionals often work across documents, spreadsheets, and presentation-style artifacts, but it should not be interpreted as a guarantee for any institution’s proprietary workflows. The only defensible way to use such a benchmark is as a reason to run institution-specific evaluations: representative models, real templates, redacted historical tasks, edge cases, and reviewer-scored outputs.
Astra-assisted financial reasoning is strongest when the task has a clear structure and measurable acceptance criteria. Examples include reconciling quarterly line items, summarizing management commentary by topic, drafting first-pass peer narratives, checking whether a slide footnote matches a table, or producing a sensitivity table from stated assumptions. It is riskier when the task requires suitability analysis, investment recommendations, legal interpretation, material nonpublic information judgment, or determinations that are subject to regulated sign-off. In those cases, the assistant can prepare evidence, but the accountable professional must decide.
Institutions should require the assistant to separate facts, calculations, assumptions, and judgments. A good first-pass response might label “source-backed facts” for figures extracted from transcripts or financial statements, “derived calculations” for growth rates and margins, “analyst assumptions” for forecast drivers, and “draft judgment” for the narrative view. This structure allows a reviewer to approve a calculation while rejecting a conclusion, or to accept a sourced quote while revising the investment interpretation.
| Workflow stage | AI-assisted task | Required human control | Failure mode to test |
|---|---|---|---|
| Retrieval | Find filings, transcripts, statements, fundamentals, private-company records, or news items relevant to a task. | Confirm entitlement, source class, issuer identity, period, and citation coverage. | Retrieving a similarly named company, wrong fiscal period, stale transcript, or non-permitted data source. |
| Extraction | Pull metrics, management statements, transaction details, covenant language, or peer data. | Reconcile extracted values to authoritative sources and document any adjustments. | Mixing reported and adjusted metrics, omitting footnotes, or losing negative qualifiers. |
| Reasoning | Calculate growth, margins, sensitivities, valuation ranges, or thematic summaries from defined inputs. | Review formulas, assumptions, scenario logic, and domain interpretation. | Producing a polished conclusion from incomplete, inconsistent, or misaligned inputs. |
| Artifact generation | Create drafts of spreadsheets, memos, Word documents, or PowerPoint-style slides using firm templates. | Apply supervisory, compliance, conflicts, legal, and client-approval workflows before use. | Creating client-ready-looking material before citations, approvals, and restricted-list checks are complete. |
Documents, Spreadsheets, and Slides: Treat Artifacts as Drafts Until Approved
OpenAI says administrators can publish Excel, Word, and PowerPoint templates and style guides for ChatGPT for Financial Services. That capability is significant because financial workflows often fail not at the “answer” stage but at the packaging stage: a model output must fit a firm’s valuation model conventions, memo structure, disclosure language, slide formatting, branding rules, and review workflow. Firm templates can reduce rework and inconsistency, but they also increase the risk that unapproved analysis looks final because it appears in the firm’s official format.
A document-generation workflow should therefore include a visible draft status, a source appendix, and a reviewer checklist. A Word-style investment memo draft should identify which sections were AI-drafted, which figures were retrieved from cited sources, which judgments remain analyst-authored, and which approvals are pending. A spreadsheet draft should expose formulas, assumptions, linked sources, and manual overrides rather than hiding the reasoning in narrative text. A slide draft should keep citations and calculation notes close enough to the claim that a reviewer can validate the story without reconstructing the entire workbook.
A practical control is to require a “no orphan numbers” rule for generated artifacts. Every material number in a memo, spreadsheet, or slide must map to a source citation, a visible formula, or an explicitly labeled assumption. If the assistant creates a valuation bridge, for example, each enterprise value, net debt figure, EBITDA estimate, multiple, and share count should be traceable. If a number cannot be traced, it should be removed, footnoted as an assumption, or sent back for retrieval and reconciliation.
Firm Templates and Style Guides Need Governance, Not Just Branding
Publishing firm templates is not merely a productivity feature; it is a governance surface. A template can encode required disclaimers, disclosure blocks, confidentiality markings, internal-only labels, approval tables, and standard calculation formats. It can also inadvertently spread outdated language, obsolete risk factors, or formatting that encourages users to omit citations. Administrators should maintain templates as controlled documents, with owners, version history, retirement dates, and a process for emergency updates when legal, compliance, or brand requirements change.
For spreadsheet templates, governance should include locked calculation areas where appropriate, protected assumptions tabs, standardized source columns, and mandatory units and period labels. For slide templates, governance should include required footnote areas, source legends, classification labels, and placeholders for reviewer names or approval IDs where firm policy requires them. For Word templates, governance should include approved section headings, required limitations language, and prompts that force the assistant to distinguish factual summary from analytical judgment.
Recommended artifact review prompt pattern:

Before finalizing this draft, produce a review table with:
1. Every material claim or number.
2. Its source citation, formula, or stated assumption.
3. The document section, spreadsheet cell, or slide location.
4. Any uncertainty, missing period, conflicting source, or manual judgment.
5. The human reviewer or approval group required before circulation.
This pattern does not make the output compliant by itself, but it gives reviewers a structured queue. It is especially useful for supervising associates, research editors, compliance reviewers, and model-risk teams because it separates formatting quality from evidentiary quality.
Identity, Access, and Retention Controls for Financial Institutions
OpenAI identifies enterprise controls for ChatGPT for Financial Services including SAML SSO, SCIM, role-based access, configurable retention, Compliance Platform log exports, role-based control over skills and apps, read/write action controls, and multiple workspaces for information barriers. These controls should be mapped to existing identity governance rather than operated as a separate exception process. A financial institution should be able to explain who can access the workspace, which group assigned that access, what data and tools the user can reach, and how access changes are logged when a person changes role, desk, geography, or project.
SAML SSO should be treated as the authentication baseline because it lets the institution enforce centralized login policies. SCIM should be used to automate user provisioning and deprovisioning so that joiners, movers, and leavers do not depend on manual workspace cleanup. Role-based access control should reflect job function and risk profile: an investment banking analyst working on live mandates, an equity research associate, a compliance reviewer, and a technology administrator should not receive identical data, tool, or action permissions.
Configurable retention should be set according to records-management, litigation-hold, supervisory, and privacy requirements. OpenAI says business data is not used to train models by default and is encrypted at rest and in transit, but those statements do not remove the institution’s obligation to determine how long chats, files, generated artifacts, and logs should be retained under its own policies. Retention settings should be reviewed with legal, compliance, information security, and records-management teams before production use, especially for regulated communications and materials that may become part of a deal file or research record.
The Compliance Platform is important because administrators need auditable evidence, not informal assurances. OpenAI’s help materials describe a compliance platform for Enterprise and Edu customers; for financial institutions, the relevant operating model is to export logs into the firm’s existing surveillance, e-discovery, security information and event management, or governance archive where applicable. Log export alone is not surveillance; teams must define monitored events, escalation thresholds, reviewer responsibilities, and retention treatment for both prompts and outputs where policy requires.
Skills, Apps, and Read/Write Controls Are a Conduct-Risk Boundary
Role-based control over skills and apps matters because the risk of a ChatGPT workflow changes sharply when the assistant can move from reading information to taking action. A read-only research assistant that summarizes cited transcripts creates a different risk profile from an assistant that can update a document repository, send information to another app, modify a spreadsheet, or interact with an internal workflow tool. OpenAI’s launch notes read/write action controls, and financial institutions should use that distinction to separate analysis from execution.
A conservative rollout should begin with read-only access for high-value retrieval and drafting tasks, then add write actions only after the institution has approved tool-specific scopes, logging, error handling, and human confirmation. For example, allowing a user to draft a deal-comps slide is lower risk than allowing an automated workflow to save a file into a transaction folder, update a client-ready deck, or trigger a distribution step. Any action that changes a record, communicates externally, affects a client, or enters a regulated workflow should require explicit human approval and a durable audit trail.
| Control area | Recommended deployment question | Approval owner |
|---|---|---|
| Skills | Which specialized capabilities are permitted for each role, desk, or workspace? | Business owner with compliance and security review. |
| Apps | Which connected applications can the assistant access, and are they read-only or write-capable? | Application owner and identity governance team. |
| Read actions | Which data classes can be retrieved, cited, summarized, or included in artifacts? | Data owner, licensing team, and compliance. |
| Write actions | What records, repositories, tickets, spreadsheets, or documents can be modified? | Workflow owner, legal/compliance, and technology risk. |
Information Barriers and MNPI Safeguards
OpenAI says multiple workspaces can be used for information barriers. In financial services, that capability should be aligned to existing wall-crossing, restricted-list, watch-list, and deal-team controls rather than used as an informal foldering mechanism. An information barrier is effective only if workspace membership, data connectors, templates, logs, and permitted actions reflect the barrier. A user who can retrieve restricted transaction material in one workspace and then summarize it into a public-research draft in another has created the type of cross-contamination the barrier is meant to prevent.
The article outlines enterprise security checks for ChatGPT Work, emphasizing data governance, access control, and audit compliance before deployment. The complete 3 Enterprise Security Checks Before Deploying ChatGPT Work — Data Governance, Access Control, and Audit Compliance article provides the destination-specific detail for this section’s Information Barrier Governance decision because information barriers in financial services depend on access control, data governance, and auditability, which are the central topics of this target article.
Material nonpublic information safeguards should start with data classification at ingestion and continue through retrieval, reasoning, and artifact generation. Users should be trained not to paste MNPI into unrestricted workspaces, and administrators should configure workspaces so that private-side data is isolated from public-side research workflows. Where policy allows AI assistance on MNPI-bearing work, the institution should require human approval before any output is shared outside the authorized deal or project team, and logs should support post-hoc review of who accessed or generated what.
A useful MNPI control is to require the assistant to label uncertainty about information status. If a user asks for a research-style summary of a company that is also the subject of a private mandate, the assistant should not decide whether information is public, restricted, or wall-crossed. Instead, the workflow should force a compliance check, require the user to identify the permitted source set, and block or escalate output generation when the source status is unclear. This approach treats the model as a drafting and retrieval aid, not as an arbiter of securities-law obligations.
Model Validation, Evaluation Sets, and Approval Gates
Model validation for ChatGPT for Financial Services should be task-specific. A single approval for “use of GPT-6 Astra” is too broad because the risk differs across transcript summarization, private-company screening, valuation modeling, covenant extraction, market-news briefing, and client-deck drafting. Each use case should have an owner, intended users, permitted data sources, prohibited uses, test cases, accuracy thresholds or qualitative acceptance criteria, required citations, escalation paths, and records of reviewer sign-off.
Institutions should build evaluation sets from historical tasks that represent real complexity: restatements, renamed issuers, multiple share classes, non-calendar fiscal years, discontinued operations, conflicting provider values, private-company data gaps, non-GAAP adjustments, and ambiguous management commentary. Outputs should be scored by domain reviewers for source correctness, calculation correctness, period alignment, disclosure quality, and unsupported inference. A model that performs well on clean examples may still be unsuitable for production if it fails on edge cases that are common in the firm’s coverage universe.
Human approvals should be explicit at the point where an output leaves the exploratory workspace or becomes part of a regulated record. A draft spreadsheet can be AI-assisted; a valuation model used in a fairness process, investment committee package, or client recommendation needs accountable human review. A research note can be AI-drafted; publication still requires the institution’s editorial, supervisory, disclosure, conflicts, and regulatory procedures. A client presentation can be generated from templates; circulation should remain subject to the same approval rules that apply to human-created materials.
Operational rule: citations, templates, and enterprise controls reduce friction and improve reviewability, but they do not transfer accountability from the regulated professional to the model. Treat every AI-assisted artifact as a draft until the required human, supervisory, compliance, and business approvals are complete.
The safest production pattern is a layered approval model. First, the user confirms that the prompt used the correct source universe and workspace. Second, a domain reviewer validates facts, calculations, and reasoning. Third, compliance or supervisory review applies where policy requires it. Fourth, model-risk or technology-risk teams periodically review failure patterns, logs, and evaluation results. This layered design lets the institution benefit from Astra-assisted retrieval and artifact generation while preserving the governance boundaries that financial services workflows require.
Pilot Framework for Eligible Financial Institutions
A useful pilot should treat ChatGPT for Financial Services as a governed work-product environment, not as a shortcut around research, banking, risk, legal, or supervisory obligations. OpenAI describes the product as available to eligible financial institutions through sales or account teams, with built-in financial data, GPT-6 Astra, optimized provider connections, firm templates, citations, and enterprise controls. That combination is operationally meaningful, but it still requires a structured pilot that tests entitlement boundaries, evidence quality, artifact quality, and approval workflows before any institution expands usage to regulated production processes.
The pilot owner should define one accountable business sponsor, one technology owner, one compliance reviewer, one information-security reviewer, one data-licensing reviewer, and one front-office subject-matter lead. The goal is to decide whether specific workflows can be accelerated with acceptable residual risk, not to prove that every analyst, banker, or portfolio professional should use the system for every task. A tight pilot with measured pass/fail criteria is more useful than a broad experiment that produces anecdotes but no promotion decision.
1. Select Use Cases by Risk, Evidence Availability, and Reviewability
Start with tasks where the firm can compare the AI-assisted output against authoritative materials and where human review is already part of the workflow. Suitable first candidates may include earnings-call transcript summarization, public-company comparable-company table drafting, market-update slide preparation, private-company profile assembly from licensed data, or first-pass research-note evidence extraction. Avoid first-wave use cases that require personalized recommendations, discretionary trading decisions, client suitability determinations, unresolved MNPI judgments, or unreviewed external publication.
| Use-case category | Good pilot fit | Reason to defer | Required reviewer |
|---|---|---|---|
| Transcript and filing summaries | High, if source citations are sampled and reconciled | Defer if summaries will be sent externally without analyst sign-off | Research analyst or banking coverage lead |
| Financial model support | Moderate, if formulas, periods, and source fields are validated | Defer if outputs can overwrite approved models without review | Model owner and finance-domain reviewer |
| Client-ready slides | Moderate, if templates and citations are controlled | Defer if branding, disclosures, or legal legends are not enforced | Banking, legal, compliance, and presentation standards owner |
| Investment recommendation drafting | Low for an initial pilot | High conduct, suitability, conflicts, and supervisory risk | Research supervision and compliance leadership |
Each pilot use case should have a written task contract. The contract should state the permitted input types, permitted sources, output format, reviewer role, approval path, prohibited uses, and escalation triggers. A practical rule is that the first pilot should be “review amplification,” not “decision automation”: the system may assemble, summarize, format, and cite, while humans decide whether the result is complete, accurate, suitable, and approved for its destination.
2. Verify Data Entitlements Before Testing Output Quality
OpenAI says the financial-services product includes data from providers named in the launch, including Daloopa, PitchBook, LSEG News, and Crunchbase, and that separate entitlement integrations are being developed for existing subscriptions from providers such as S&P Capital IQ, LSEG, MSCI, Dow Jones Factiva, and Moody’s. A pilot must separate included data from subscription-entitled data and from the broader connector ecosystem. Those are different access channels with different contractual, operational, and compliance implications.
The data-licensing reviewer should build an entitlement matrix before users test live workflows. For each dataset, record whether it is included in the product, dependent on the firm’s own subscription, available through a connector, unavailable, or restricted for the pilot. Then map each use case to the data it requires. If a workflow needs a subscription integration that is still in development or not enabled for the institution, the pilot should not assume the data can be retrieved simply because the provider name appears in the launch announcement.
Recommended entitlement matrix fields:
- Provider name
- Dataset or content type
- Included, subscription-entitled, connector-based, unavailable, or restricted
- Permitted user population
- Permitted workflow
- Citation expectations
- Redistribution restrictions
- Required supervisory review
- Contract owner
- Pilot decision: allow, allow with controls, or block
Entitlement testing should include negative tests. A user in one business line should not be able to retrieve content reserved for another population if the institution relies on information barriers or subscription scoping. A user should not treat cited output as redistributable unless the underlying license permits the intended use. If the institution cannot determine whether a source can be used in a client deliverable, the pilot should classify that output as internal draft material only.
3. Sample Evidence, Not Just Final Answers
Granular citations are one of the most important financial-services features described by OpenAI, because they can make retrieval auditable. They do not, however, prove that the answer is complete, that the cited passage supports the claim, that all relevant sources were considered, or that the user may rely on the content for a regulated purpose. The pilot should therefore evaluate evidence trails, not only final prose.
For each test output, reviewers should sample a fixed number of claims and classify them as fully supported, partially supported, unsupported, contradicted, stale, or unreviewable. A claim is fully supported only when the citation points to the correct source, the cited material actually supports the statement, the period and entity are correct, and the output does not omit a material qualifier. If a model says revenue increased year over year, the reviewer should verify the company, fiscal period, currency, restatement status, and source field before accepting the sentence.
| Evidence category | Definition | Pilot treatment |
|---|---|---|
| Fully supported | The cited source directly supports the claim with correct entity, period, and context. | Count toward accuracy threshold. |
| Partially supported | The citation is relevant but misses a qualifier, period, or calculation detail. | Require correction and root-cause tagging. |
| Unsupported | The cited source does not substantiate the claim. | Fail the sampled claim and review adjacent claims. |
| Contradicted | The citation or another authoritative source conflicts with the output. | Escalate as a material accuracy issue. |
| Unreviewable | The reviewer cannot access or identify the underlying evidence. | Do not approve for external or regulated use. |
The article explains OpenAI’s Frontier Governance Framework as an operational and regulatory approach to compliance and safety for enterprise AI deployments. The complete OpenAI’s Frontier Governance Framework Explained: What Enterprise AI Teams Need to Know in 2026 article provides the destination-specific detail for this section’s AI Model Governance for Finance decision because it is semantically appropriate for AI model governance because it focuses on governance frameworks, compliance, and safety for frontier AI models used by enterprises.
4. Validate Firm Templates and Style Guides as Controlled Assets
OpenAI says administrators can publish Excel, Word, and PowerPoint templates and style guides. That capability is valuable only if templates are treated as controlled assets. A presentation template should include the latest branding rules, disclosure placement, approved chart conventions, footer requirements, and restrictions on client names or transaction status. A spreadsheet template should distinguish input cells, model-generated drafts, locked formulas, and review sign-offs. A document template should enforce required legends, citation format, and approval metadata.
Template validation should have two tracks. The first track checks formatting fidelity: whether outputs follow the approved layout, naming conventions, footnote style, and document structure. The second track checks control fidelity: whether required disclosures remain present, whether restricted sections are not overwritten, whether formulas are preserved, and whether the artifact clearly indicates draft status before approval. A beautiful deck that drops a required disclaimer is a failed pilot output, not a partial success.
5. Set Accuracy Thresholds Before Users Produce Pilot Outputs
Accuracy thresholds should be set before testing begins so the pilot does not drift toward anecdotal acceptance. The institution should define separate thresholds for factual claims, numerical values, citation validity, formatting compliance, and workflow completion. For example, the firm may require no contradicted material claims, a high pass rate for sampled factual statements, zero unresolved entitlement violations, and complete reviewer sign-off before any output leaves the pilot group. The exact thresholds should be chosen by the institution’s risk owners, not copied from a vendor benchmark.
OpenAI reports a vendor-published OfficeQA Pro result for GPT-6 Astra compared with GPT-5.6 Sol, and the financial-services launch includes design-partner statements. Those statements are useful context for why the product exists, but they do not establish an institution’s acceptable error rate, approval policy, or productivity return. A pilot threshold must be based on the firm’s own documents, data licenses, review standards, and downstream risk.
6. Run Compliance Review as a Workflow Test, Not a Final Rubber Stamp
Compliance review should occur during pilot design, during test-case selection, after evidence sampling, and before promotion. Reviewers should examine whether outputs could be considered research, investment advice, marketing material, client communications, internal analysis, or operational support. That classification affects disclosures, supervision, archiving, retention, conflicts review, and permissible distribution. The same AI-assisted paragraph may be low risk in an internal briefing and high risk in a client-facing note.
The governance features named by OpenAI, including SAML SSO, SCIM, role-based access, configurable retention, Compliance Platform log exports, role-based control over skills and apps, read/write action controls, and multiple workspaces for information barriers, should be tested against concrete scenarios. The pilot should confirm that the right users have access, the wrong users do not, logs are exportable through the institution’s approved process, and workspace boundaries align with the firm’s information-barrier design. Do not assume that a control exists in policy simply because it is mentioned in a product description; verify it in the deployed environment.
7. Measure Task Economics Without Treating Productivity as the Only Outcome
Task economics should compare the current process with the AI-assisted process across elapsed time, human review time, rework, licensing complexity, supervisory burden, and incident cost. A pilot that saves drafting time but doubles review time may still be useful for deadline compression, but it should not be reported as a pure productivity gain. Conversely, a workflow that produces fewer formatting errors or more consistent citations may be valuable even if time savings are modest.
Recommended pilot economics calculation:
Net value =
  avoided drafting time
+ avoided formatting/rework time
+ faster evidence retrieval value
- additional reviewer time
- entitlement administration time
- compliance and audit overhead
- remediation time for failed outputs
- platform, implementation, and operating costs
The institution should also distinguish one-time learning costs from recurring operating costs. Initial template cleanup, entitlement mapping, reviewer training, and prompt standardization may be front-loaded. Ongoing costs include user support, exception review, access recertification, output sampling, and periodic validation after product or workflow changes.
8. Define Incident Handling Before the First Production-Like Test
Incident handling should be written before pilot users begin production-like tasks. Trigger events should include suspected entitlement leakage, cited evidence that does not support a material claim, external distribution of an unapproved output, possible MNPI exposure, unauthorized connector use, template disclosure failure, retention misconfiguration, or user attempts to bypass review. Each incident type should have an owner, severity level, containment action, evidence-preservation requirement, and decision rule for whether the pilot pauses.
A practical containment pattern is to preserve the output, source citations, prompt or task description, user identity, workspace context, approval status, and distribution history; stop further distribution; notify the designated compliance and technology owners; and classify the root cause. Root causes should distinguish retrieval failure, reasoning error, stale data, entitlement configuration, template defect, user misuse, inadequate instructions, and reviewer miss. This classification matters because the remedy may be a template fix, access change, training update, use-case removal, or escalation to the platform vendor through the firm’s support process.
9. Promotion Criteria: Move Use Cases, Not the Entire Product, Forward
Promotion should be use-case specific. A transcript-summary workflow may pass while a model-update workflow remains blocked. A PowerPoint drafting workflow may pass for internal committee decks but fail for client-facing pitchbooks until disclosures, approval routing, and source restrictions are resolved. The promotion decision should document the allowed users, allowed inputs, allowed outputs, required review steps, sampling cadence, incident triggers, and rollback procedure.
| Promotion gate | Pass condition | Failure response |
|---|---|---|
| Entitlements | All required datasets are licensed, enabled, and scoped to approved users. | Block or restrict the workflow until access is resolved. |
| Evidence quality | Sampled claims meet the firm’s support and citation thresholds. | Revise instructions, sources, or review requirements. |
| Template control | Required disclosures, formulas, and formatting survive generation. | Fix templates before broader use. |
| Compliance approval | Workflow classification, retention, supervision, and distribution rules are approved. | Defer promotion and document unresolved obligations. |
| Operating economics | Measured value exceeds review, remediation, and administration costs. | Narrow the use case or stop the pilot. |
What the Launch Does Not Prove
The launch does not prove that ChatGPT for Financial Services is available to every firm, every ChatGPT plan, or every financial professional. OpenAI describes it as available to eligible financial institutions through sales and account teams. The launch also does not prove that every named data-provider integration is live for every customer; OpenAI distinguishes included data from entitlement integrations that are being developed for existing subscriptions.
The launch does not prove that citations eliminate hallucination risk, licensing risk, or review obligations. Citations improve traceability, but institutions still need source reconciliation, period checks, calculation review, conflicts review, MNPI controls, suitability analysis where applicable, and regulated approvals. A cited answer can still be incomplete, stale, misinterpreted, or unsuitable for the intended audience.
The launch does not prove that vendor-published benchmark results or design-partner comments will translate into the same accuracy, cost, or productivity outcomes at another institution. Differences in templates, data entitlements, approval workflows, analyst expectations, and information barriers can materially change results. Each firm needs its own validation set and promotion thresholds.
The launch does not transfer accountability from licensed professionals, supervisors, committees, or regulated entities to a model. GPT-6 Astra and ChatGPT Work capabilities can support research and banking workflows, but they do not approve investment conclusions, validate models, authorize distribution, or determine legal compliance. The safest adoption pattern is disciplined acceleration: use the system to draft, retrieve, compare, format, and explain, while retaining human responsibility for judgments and approvals.
Conclusion
ChatGPT for Financial Services is best understood as a purpose-built financial-work environment that combines GPT-6 Astra, built-in premium data, developing entitlement integrations, granular citations, firm-controlled templates, and enterprise governance controls. Its value will depend less on whether users can generate impressive drafts and more on whether institutions can prove that specific workflows respect data licenses, preserve information barriers, produce reviewable evidence, maintain approved templates, and improve task economics without weakening compliance.
Eligible institutions should pilot narrowly, measure rigorously, and promote only the workflows that pass entitlement, evidence, template, compliance, incident-response, and economic gates. That approach lets teams capture real drafting and research support while avoiding the common failure mode of treating AI output as approved analysis. In financial services, the durable advantage is not merely faster generation; it is faster generation inside a control framework that can withstand supervisory, client, audit, and legal review.
Access 40,000+ AI Prompts for ChatGPT, Claude & Codex — Free!
Subscribe to get instant access to our complete Notion Prompt Library — the largest curated collection of prompts for ChatGPT, Claude, OpenAI Codex, and other leading AI models. Optimized for real-world workflows across coding, research, content creation, and business.
Useful Links
- OpenAI: Introducing ChatGPT for Financial Services
- OpenAI: GPT-6 Astra and Next-Generation Work
- OpenAI Developers: GPT-6 Astra Model Documentation
- OpenAI Help: ChatGPT Work and Codex
- OpenAI Help: Compliance Platform for Enterprise and Edu Customers
